A team I know filled a backend role in 38 days. Everyone was happy. The number beat the target, it went into the quarterly review as a win, and the recruiter got a thank you they had earned.
Five months later, that same engineer still could not touch the billing service without someone sitting next to them. They were still waiting on access to a dashboard. They were still asking which of the three deploy scripts was the real one.
The hiring metric closed in March. The problem it was meant to solve stayed open until August.
Most companies measure the first half of that story. Almost nobody measures the second half. And the second half is where the money goes.
What time-to-hire actually tells you#
Time-to-hire counts the days between opening a role and a signed offer. It is a real number, and it is worth knowing. It tells you whether your funnel is healthy, whether your interview loop has a traffic jam in it, and whether good candidates are getting bored and leaving.
For scale: Gem's 2026 recruiting benchmarks, built on 1.2 million hires, put engineering roles at around 62 days from open role to accepted offer. If yours is 120, something is stuck, and you should go find it.
The trouble is what the number quietly suggests, which is that the job is now done.
It is not. No engineering leader has ever needed a seat filled. What you needed was a service shipped, an on-call rotation that stops burning your senior people, and code that somebody other than its author can safely change.
Filling the seat is the start of the work, not the end of it.
When the only number you report ends at the signature, every fix you fund points at the funnel. More sourcing. Shorter loops. Faster debriefs. Nicer offer letters. None of that is wasted. All of it improves the two-month half of a process whose other half runs four to nine months in the dark.
The months nobody owns#
Ask any engineering manager how long a new hire takes to become genuinely independent. You will hear something between three and nine months. That is not a guess. It lines up with what Google's engineering productivity research team published on onboarding and ramp-up, drawn from one of the most heavily measured engineering organizations on earth.
Now ask a harder question: who is on the hook for shortening it?
Recruiting's scorecard ended at the offer. The hiring manager is judged on team delivery, and right now the new person is subtracting from it. Platform or enablement teams, if you have them, own tools rather than outcomes. So the longest and most expensive stretch of the whole hiring process sits in the gap between two org charts, and it shows.
Gallup found that only 12% of employees strongly agree their company does a good job of onboarding. Only 29% felt ready for the job once onboarding was over. Those numbers are not about paperwork. They describe a system that hands somebody a laptop and a repo and then hopes quietly.
So what do you measure instead?#
There is a fair objection here, and it deserves a straight answer. Most attempts to measure developer productivity turn into surveillance with a dashboard. Counting commits measures typing. Counting story points measures how people estimate. Neither one tells you whether someone can be trusted with a production change on a Friday afternoon.
Time-to-productivity dodges that, because it is a duration, not a score. You are not ranking people against each other. You are timing how long your own system takes to turn a capable hire into an independent one. And the variation, when you look at it, is almost always in the system.
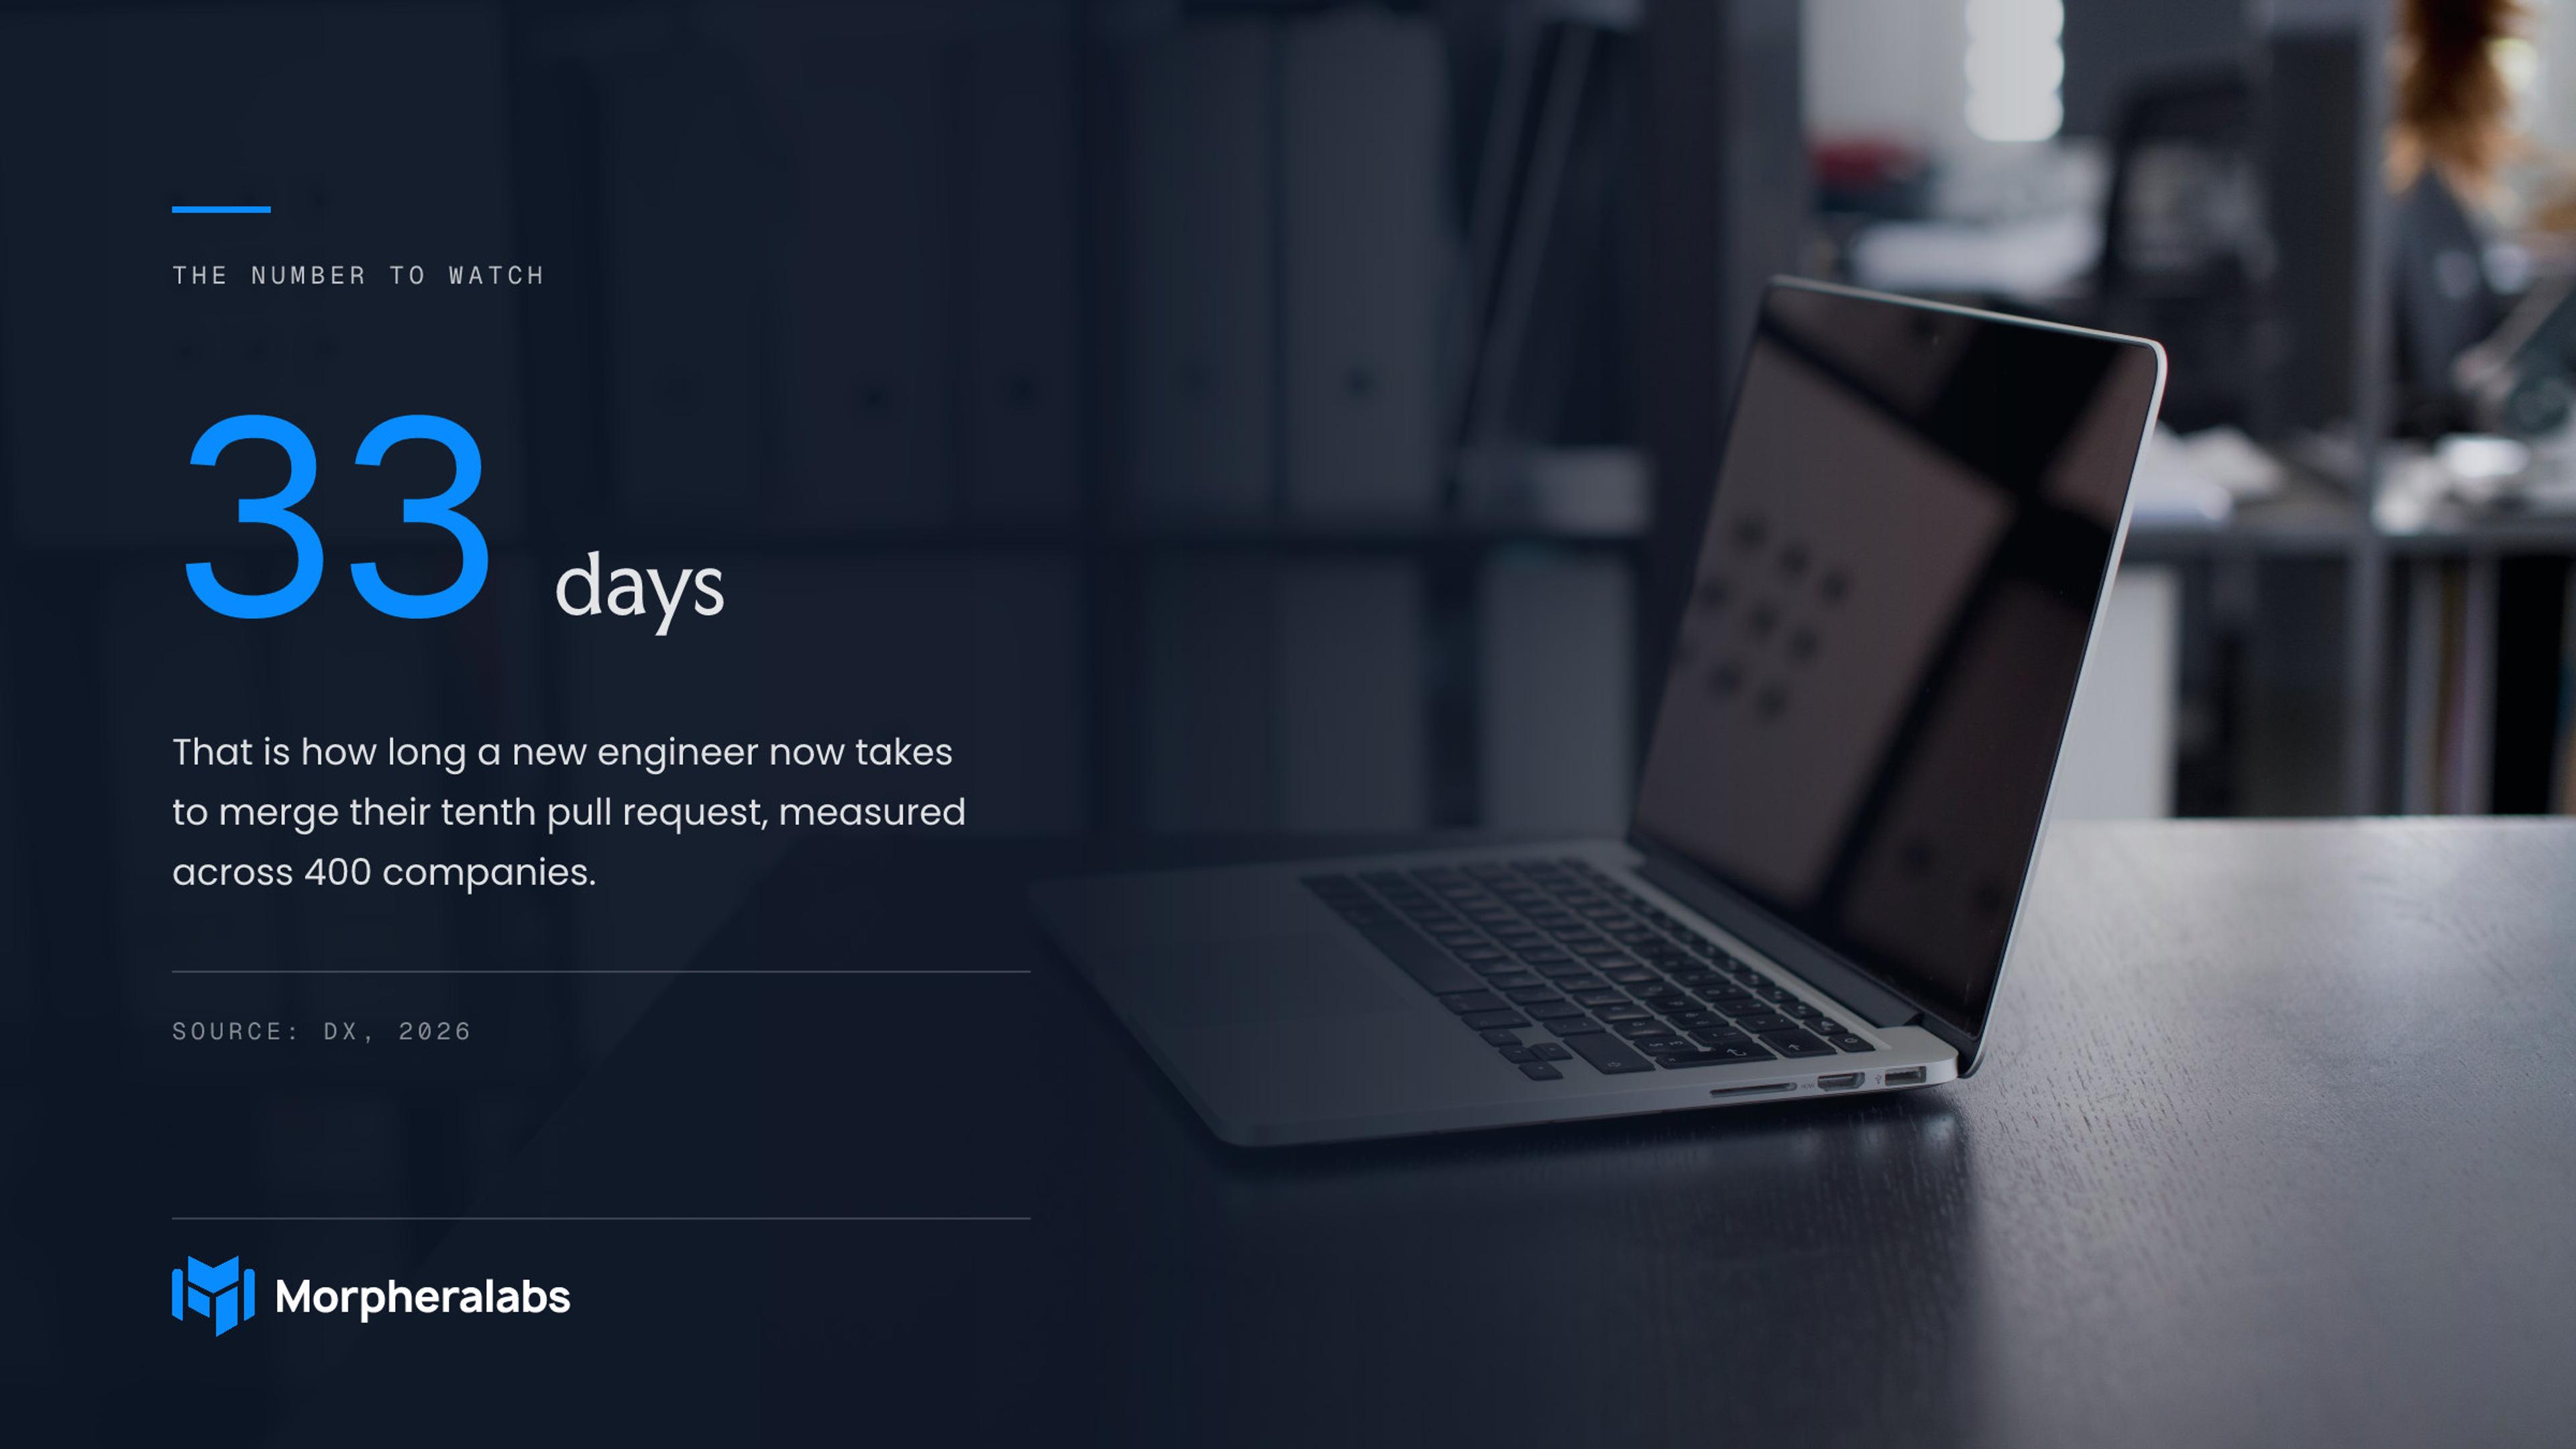
The cleanest version going around is the time-to-tenth merged pull request. DX, which tracks engineering metrics across large enterprises, put the average at 33 days in early 2026, down from 39 days at the end of 2025 and less than half of where it sat in 2024. That came from 400 companies, each with 500 or more developers.
Why the tenth and not the first? Because a first pull request can be a README fix with a buddy holding the door open. It measures welcome, not capability. By the tenth, someone has been through code review, a failing test, a merge conflict, and probably a rollback, mostly on their own. It is late enough to mean something and early enough that you can still act on it.
Four signals worth tracking#
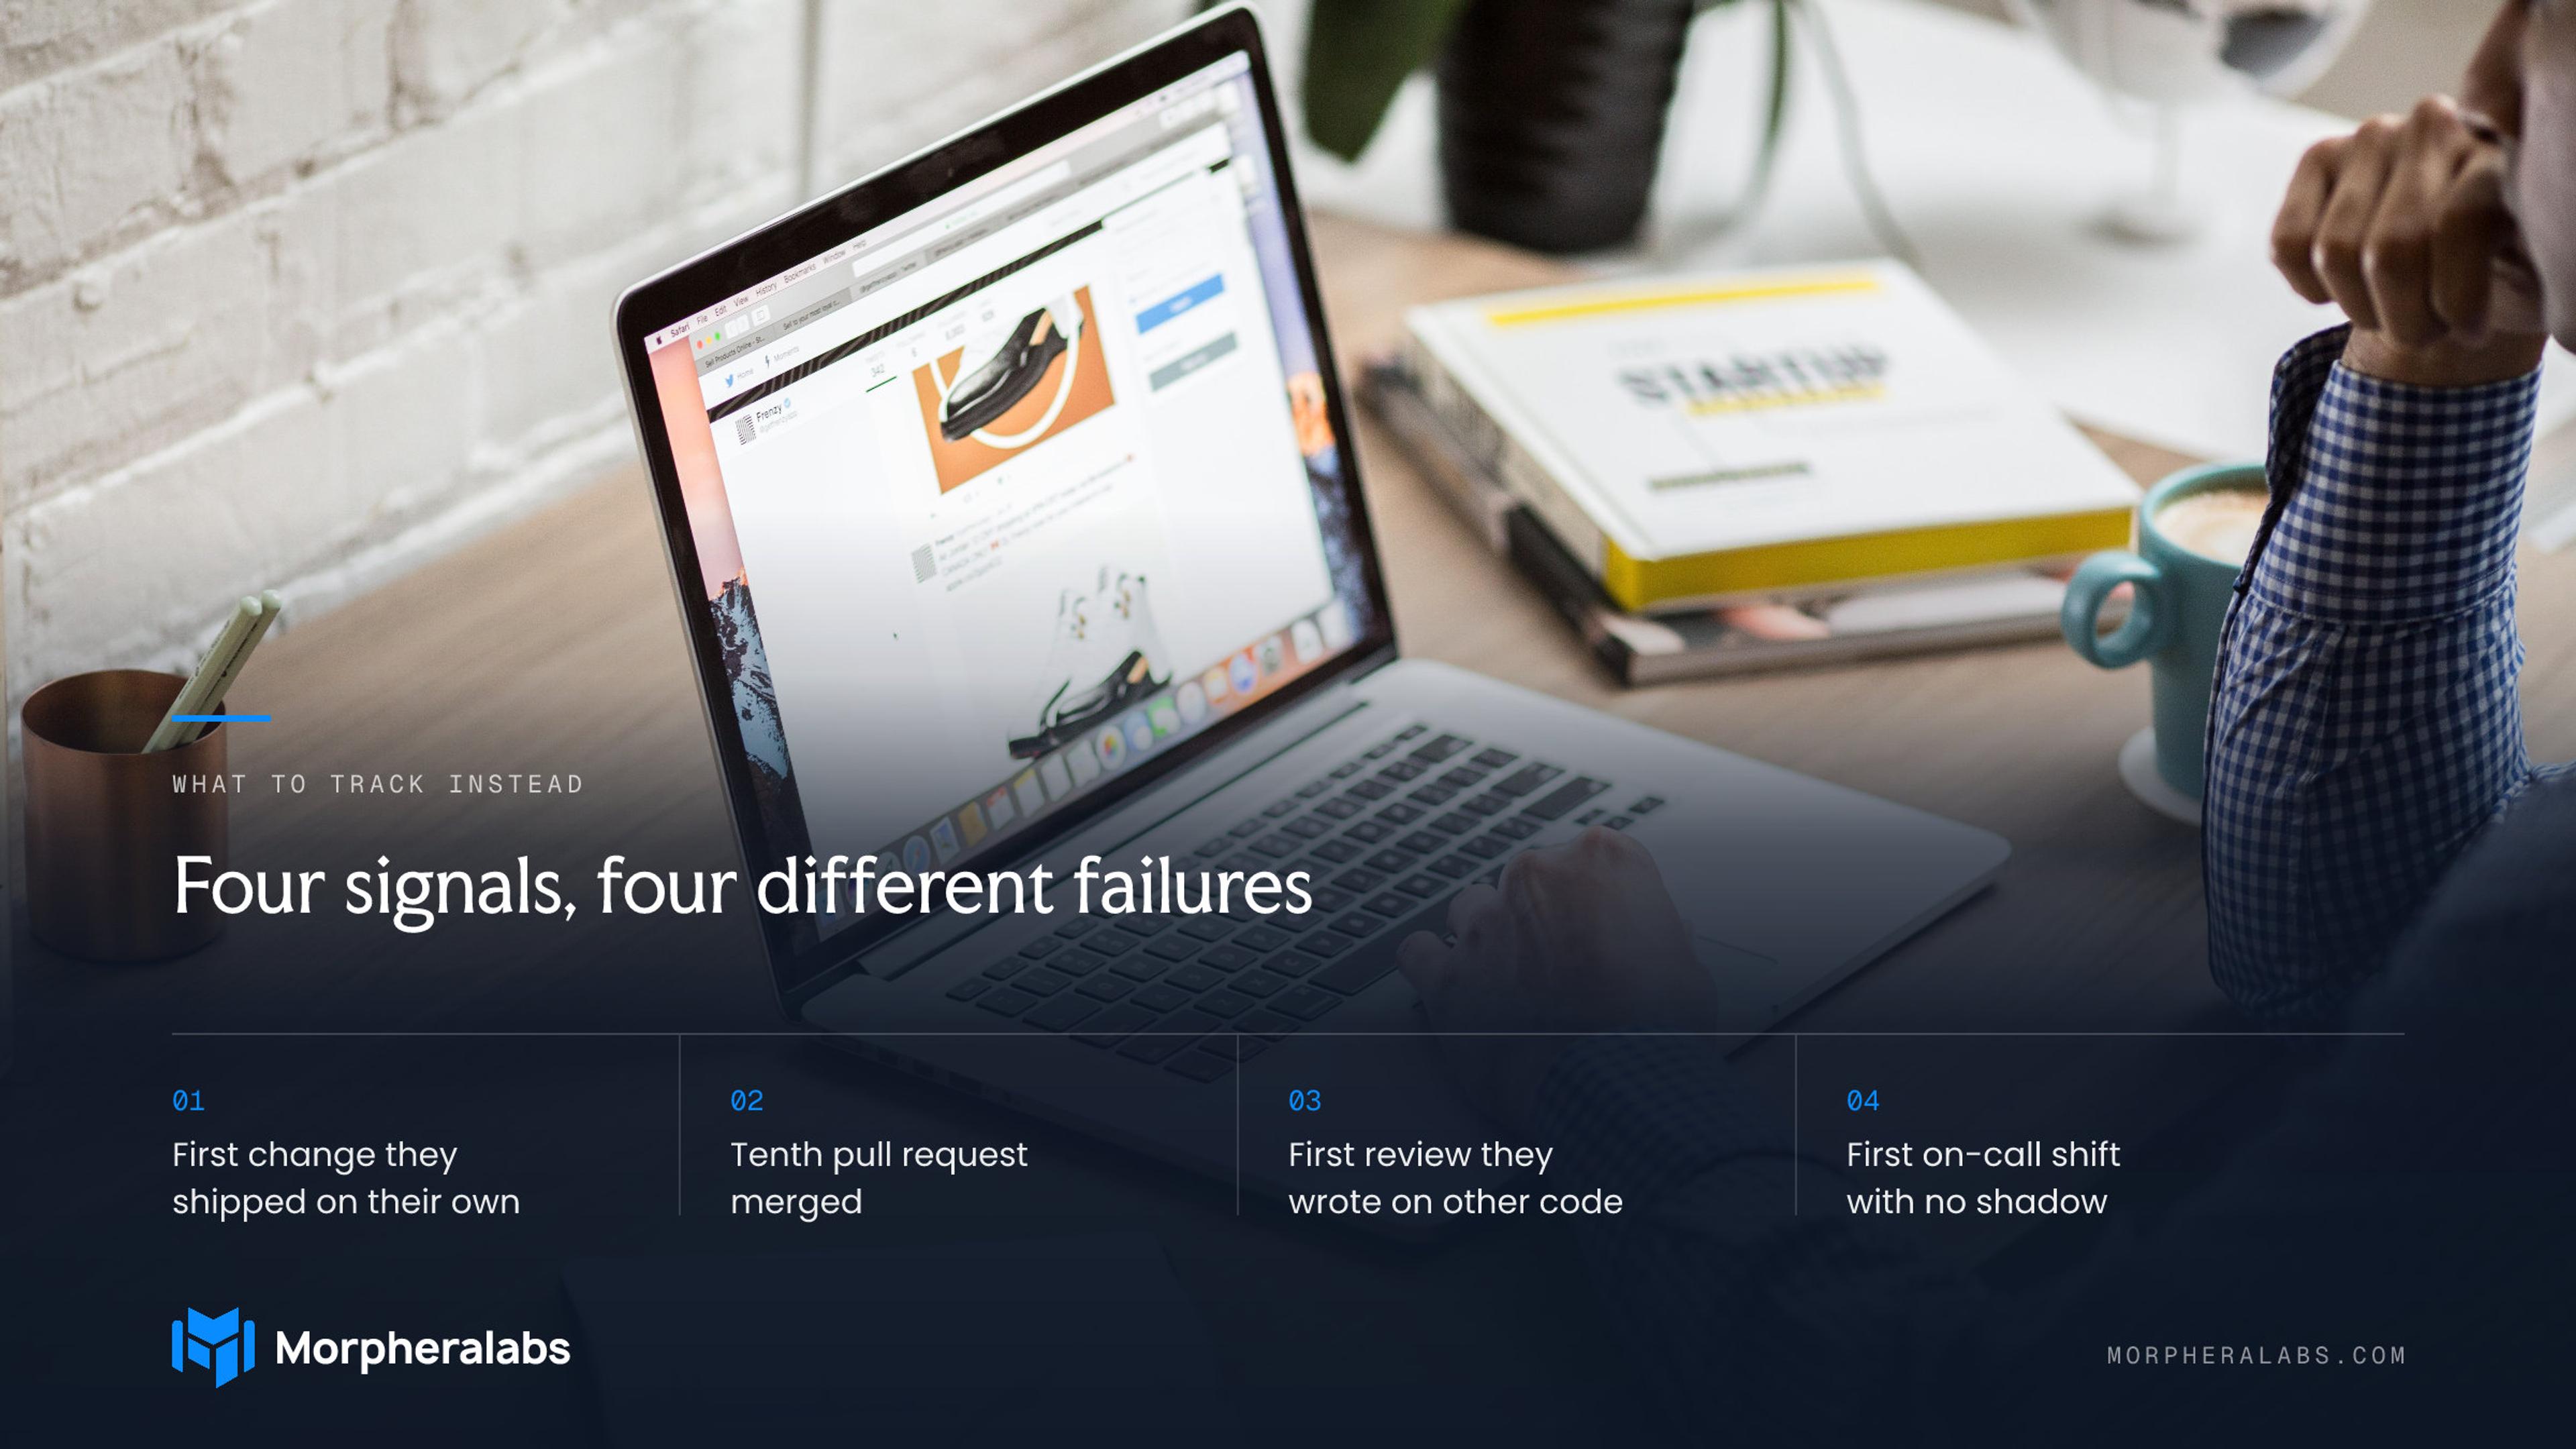
One number will not carry the whole story, and four is about as many as a team will actually keep up to date.
1. First change they shipped on their own. Not their first commit. The first change they wrote, defended in review, and pushed to production without a chaperone. This one exposes laptop setup, access requests, and deploy friction faster than any survey will.
2. Tenth merged pull request. The throughput signal. You already have it. It is sitting in your git history, and nobody has to fill in a form.
3. First review they wrote on someone else's code. The most overlooked of the four. Writing code in a strange system is possible with enough stubbornness. Reviewing someone else's code in that system means you know what good looks like locally. When a new hire starts leaving real review comments, the map is in their head.
4. First on-call shift with no shadow. The trust signal. An engineer who cannot be put on the rotation is an engineer whose load is still being carried by somebody senior. If this drifts past four months, your runbooks are the problem, not your hiring.
Plot those four across your last ten hires, and a pattern shows up fast. It is rarely about the hires.
The uncomfortable part: it is your system, not your people#
Line up ramp times across a dozen engineers, and the numbers cluster by team, by service, and by quarter far more than they cluster by individual.
The ramp is slow for reasons that are boringly specific:
- The local environment takes two days to stand up and breaks on the third.
- The test suite takes 40 minutes, so nobody runs it locally, so a newcomer's feedback loop is a CI queue.
- The decision that explains the whole data model was made in a meeting in 2023 and lives in one person's memory.
- Access goes through a ticket queue with a four-day turnaround, and a new engineer needs eleven of them.
The data on AI tooling makes the same point from another angle. In the DX numbers, engineers using AI every day hit their tenth pull request in 49 days. Engineers not using it took 91. It is tempting to read that as a story about AI. The more useful reading is that a big share of ramp time was never learning at all. It was the cost of hunting for answers about a system that could not explain itself.
A slow ramp is usually a documentation problem with a person standing in the middle of it.
That is what makes this number so much more useful than time-to-hire. A bad result hands you a list of things you can go and fix this month. A good result stays good, because the next hire inherits everything the last one paid for.
The math your finance team will actually care about#
Skip the headline dollar figure. Here is the arithmetic, and you can drop your own salary numbers into it.
| Lever | Saved per hire | Across 10 hires | What it really costs today |
|---|---|---|---|
| Faster hiring | 10 days | 100 days of empty seat | Nothing in salary. An empty chair draws no pay. |
| Faster ramp | 30 days | 300 days of a paid engineer at partial output | Salary, plus the senior hours spent unblocking them |
Three hundred days is roughly one engineer-year of capacity handed back to you, before you count what the mentors get back. Both improvements are worth having. They are not in the same weight class.
Keep time-to-hire. Just move it.#
None of this means switching the metric off. A funnel that takes 140 days to close a mid-level role is losing people to companies that take 40, and you will see it in your offer acceptance rate long before you see it anywhere else.
Time-to-hire belongs on the recruiting dashboard, next to acceptance rate and channel quality. It is a good health check for a team doing hard work. It just should not be the headline number in an engineering leadership review, because it answers a question that meeting is not asking.
How to start on Monday#
You do not need a tool, a vendor, or a budget line.
- Get a baseline. Pull your last six to ten hires out of git and your incident tool, and reconstruct the four signals after the fact. It is an afternoon of work, and the result usually ends the debate about whether the problem is real.
- Ask one question. Go to each of those engineers and ask what took them longest to work out that should have been written down somewhere. The answers overlap far more than people expect. That overlap is your first fix.
- Give it an owner. Set a target for the next three hires, put it where the team can see it, and hand it to someone with the authority to change what it exposes. A ramp metric with no owner is just another chart nobody opens.
The point of all this is not a nicer dashboard. It is that the number you report is the number people optimize. Right now, most companies are reporting one that stops just before the expensive part starts.
Morpheralabs builds data platforms, cloud infrastructure, and internal tooling for engineering teams. A lot of that work lands on the same systems that decide how fast a new person can safely change something. If that is your constraint, we are happy to talk it through.